Continuous motion
Speaking, idle, listening and thinking movements transition through overlapping blends instead of pausing between poses.
Interactive AI System / WebGL
A browser-based 3D character combining authored animation, continuous gesture blending, speech-driven lip movement, controlled AI context and graceful fallbacks.
Drag to inspect · scroll to zoom · ask a question by voice or text
Inside the project
Follow one question through the app.
Then watch how text, voice and movement connect.
Select a box to understand its part in the reply. Code links are there if you want the detail.
The card is your question. Its stop represents my work profile; the puppet is the optional 3D character and the tray is the text reply.Repeats automatically while in view. Pause to hold a moment.
The animation explains the software with a miniature theatre. It does not use your microphone or contact the assistant. Open either view for more room.
Engineering evidence
The work is the orchestration: animation, speech, interaction, rendering and failure recovery operating as one coherent browser system.
Speaking, idle, listening and thinking movements transition through overlapping blends instead of pausing between poses.
Generated or browser speech drives viseme targets and body-performance timing while protecting the first spoken words with audio readiness checks.
Answers are grounded in a maintained professional source of truth rather than pretending to know unrestricted personal information.
Text remains usable when WebGL, microphone access, speech recognition, transcription or generated audio is unavailable.
Visual direction
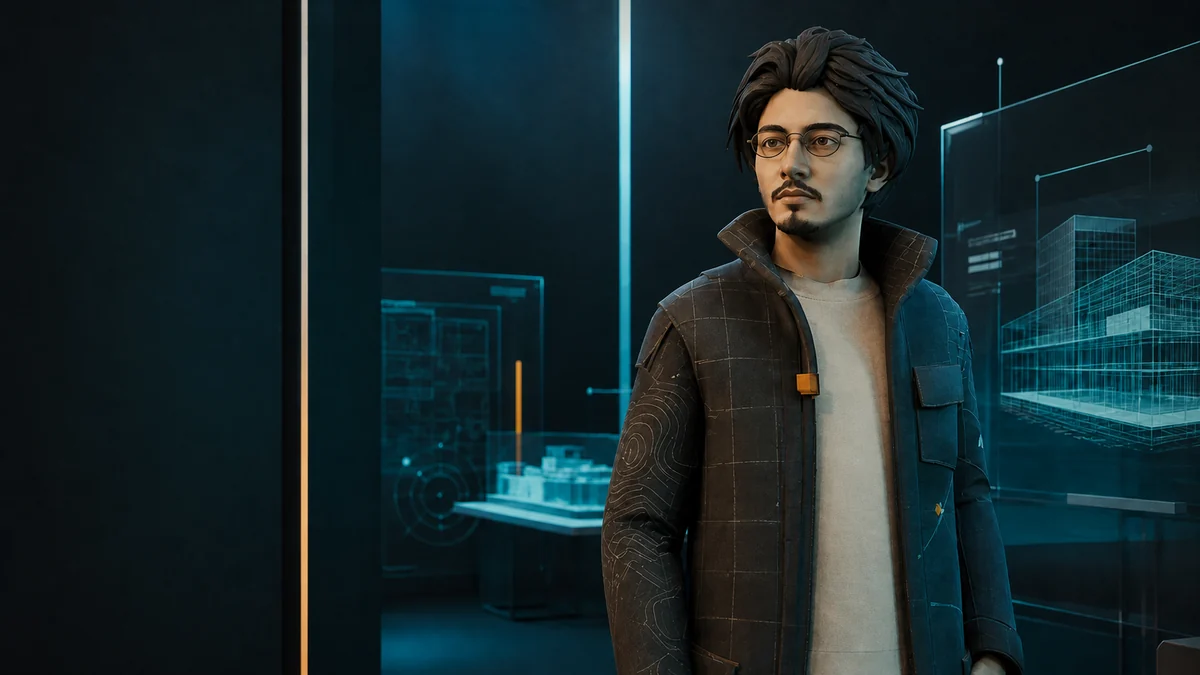
The character deliberately avoids the generic metaverse-avatar look. Layered paper materials, an architectural studio, dimensional shadows and controlled aqua-and-amber light connect the 3D experience to Sadeq's wider editorial portfolio identity.
System architecture
My contribution
I integrated Three.js rendering, responsive camera behaviour, authored animation states, speech playback and audio/transcript-driven facial targets. I blended gestures so the character does not jump straight between unrelated poses.
The assistant uses a maintained professional source of truth. Browser recognition and recorded-audio transcription offer different input paths, while the readable chat survives optional model or WebGL failure. The 3D model loads only when the viewer is requested.
Engineering, state orchestration and integration are documented separately from adapted animation resources and AI-assisted visual references. The source-code MIT licence does not grant reuse of the character likeness, model or identity artwork.
Read the asset provenance ↗The character is not a person and AI replies are not Sadeq speaking personally. Answers can be incorrect. Controlled context narrows the subject; it cannot guarantee truth. Mouth movement is approximate, not phoneme-perfect lip sync.
Microphone and speech features vary by browser and permission state. In the actual app, recordings are used to transcribe the current question; provider processing is remote. These teaching views make no microphone, recording, model-loading or provider request.
The map is a reviewed overview of source revision cc7771f, not a continuously updated dependency graph.